robotics
The Robot Learned Where Reward Had to Stop
A reachability-based safety critic cut cumulative safety cost 57% on average while improving task success by 0.13 over SafeVLA.
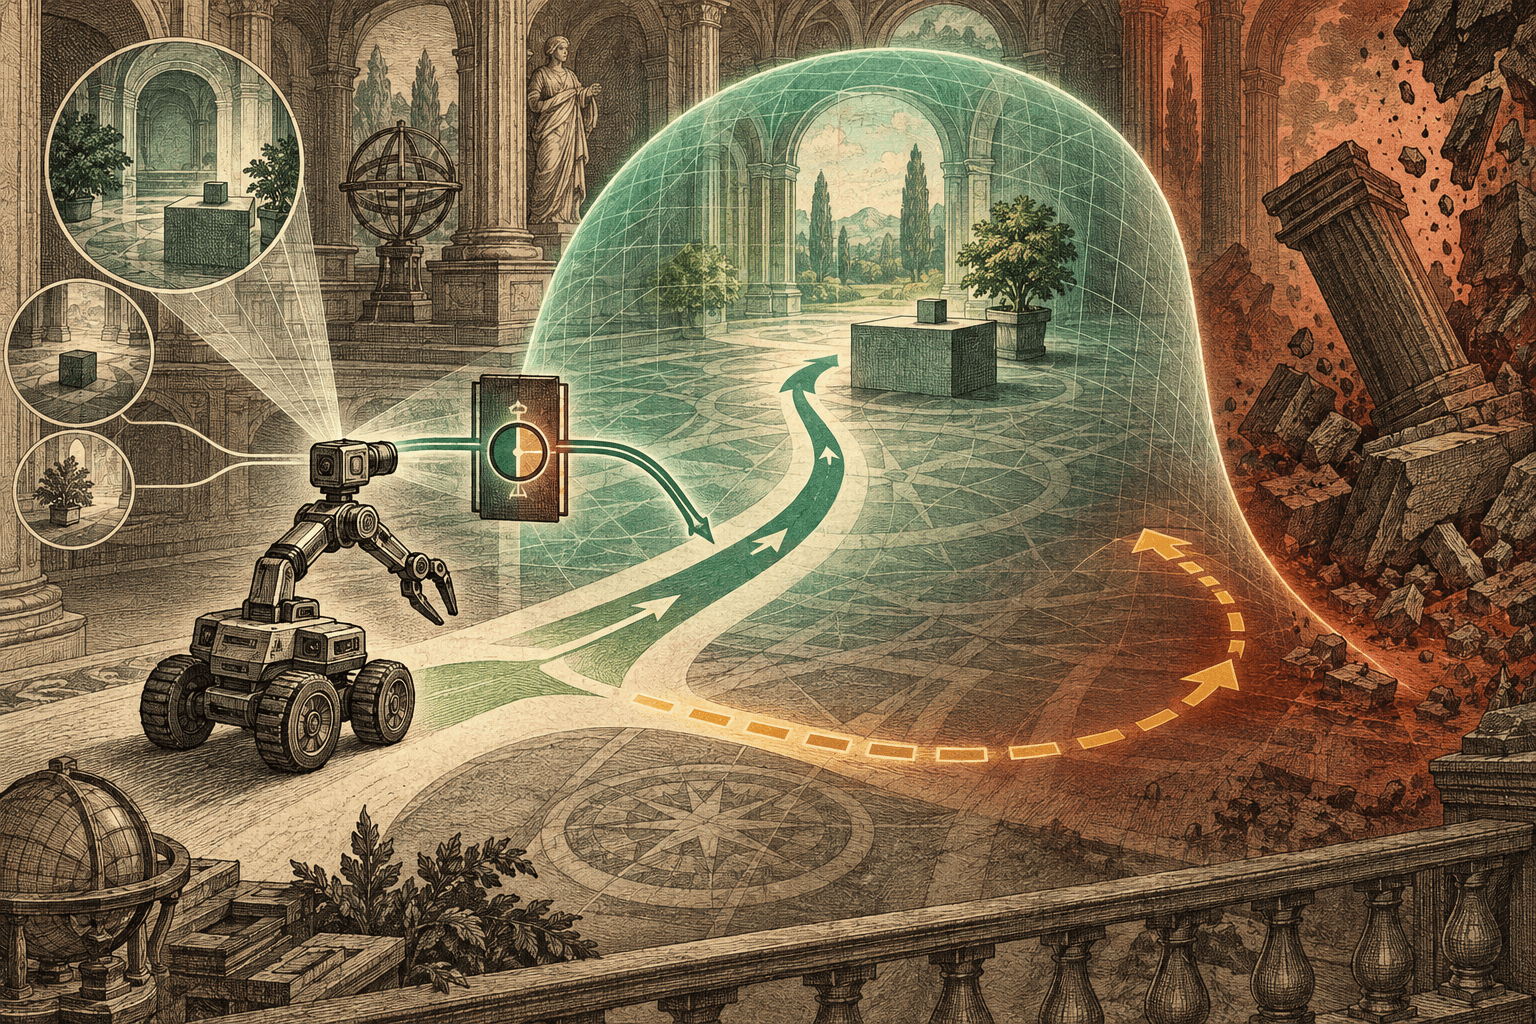
Summary
A reachability-based safety critic cut cumulative safety cost 57% on average while improving task success by 0.13 over SafeVLA.
Safety fine-tuning for vision-language-action models often treats violations as a soft penalty, forcing one objective to trade reward against risk. ShieldVLA instead learns a model-free approximation of a Hamilton–Jacobi reachability value function from visual observations. The critic separates ordinary reward optimization inside the feasible region from recovery behavior near unsafe states; rubric-based vision-language scores provide training targets without dense manual cost labels. Across five navigation and manipulation benchmarks and multiple VLA backbones, the authors report 57% lower cumulative safety cost on average and a 0.13 gain in task success over SafeVLA. Those benchmark results do not constitute a formal guarantee for an untested physical deployment.
Why it matters
A reachability-based safety critic cut cumulative safety cost 57% on average while improving task success by 0.13 over SafeVLA.
Limits and context
- Those benchmark results do not constitute a formal guarantee for an untested physical deployment.
Key claims
A reachability-based safety critic cut cumulative safety cost 57% on average while improving task success by 0.13 over SafeVLA.
Qualification: Those benchmark results do not constitute a formal guarantee for an untested physical deployment.
Evidence: source-2026-09-15-002
Sources
- arXiv preprint 2609.13231arXiv · primary research
Corrections
No corrections have been recorded for this story.