robotics
One Demonstration Became Many Ways to Grasp
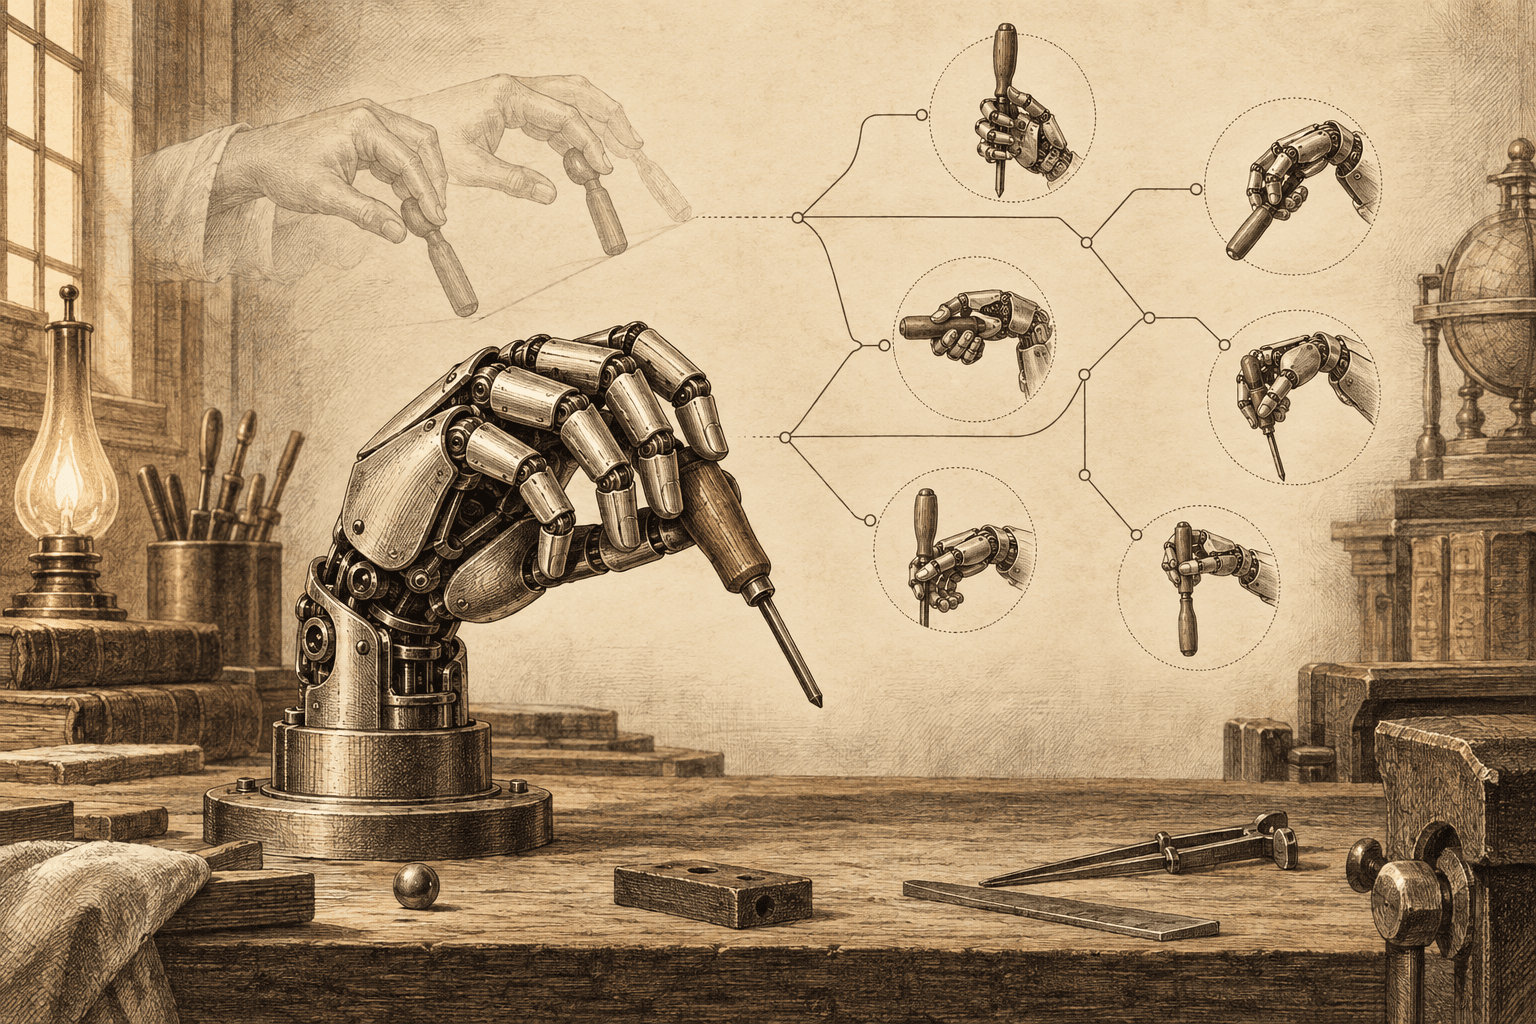
Relational scene graphs guided reinforcement learning beyond the exact poses and grasps shown in a single human video.
Summary
Relational scene graphs guided reinforcement learning beyond the exact poses and grasps shown in a single human video.
Dex-One2Many converts one human demonstration into sequential scene graphs that describe relations rather than exact motions. Those graphs generate varied reset states and dense rewards for each stage, shortening exploration while exposing the policy to new object poses, goals and grasps. Trained in simulation, the policy transferred without additional training to a real multi-fingered hand. Across five tool-use and manipulation tasks, the authors report a 6.5% advantage in seen configurations and a 71% gap over baselines in unseen scenarios. These are reported task results, not evidence that one video can teach arbitrary dexterity.
Why it matters
Relational scene graphs guided reinforcement learning beyond the exact poses and grasps shown in a single human video.
Limits and context
- These are reported task results, not evidence that one video can teach arbitrary dexterity.
Key claims
Relational scene graphs guided reinforcement learning beyond the exact poses and grasps shown in a single human video.
Qualification: These are reported task results, not evidence that one video can teach arbitrary dexterity.
Evidence: source-2026-10-10-001
Sources
- arXiv preprint 2610.12470, original v1arXiv / submitting research authors · primary research
Corrections
No corrections have been recorded for this story.